Everything Scuba
finds, marked up
One crawl uncovers the key issues impacting your search and AI visibility. Here's a selection of what Scuba finds.

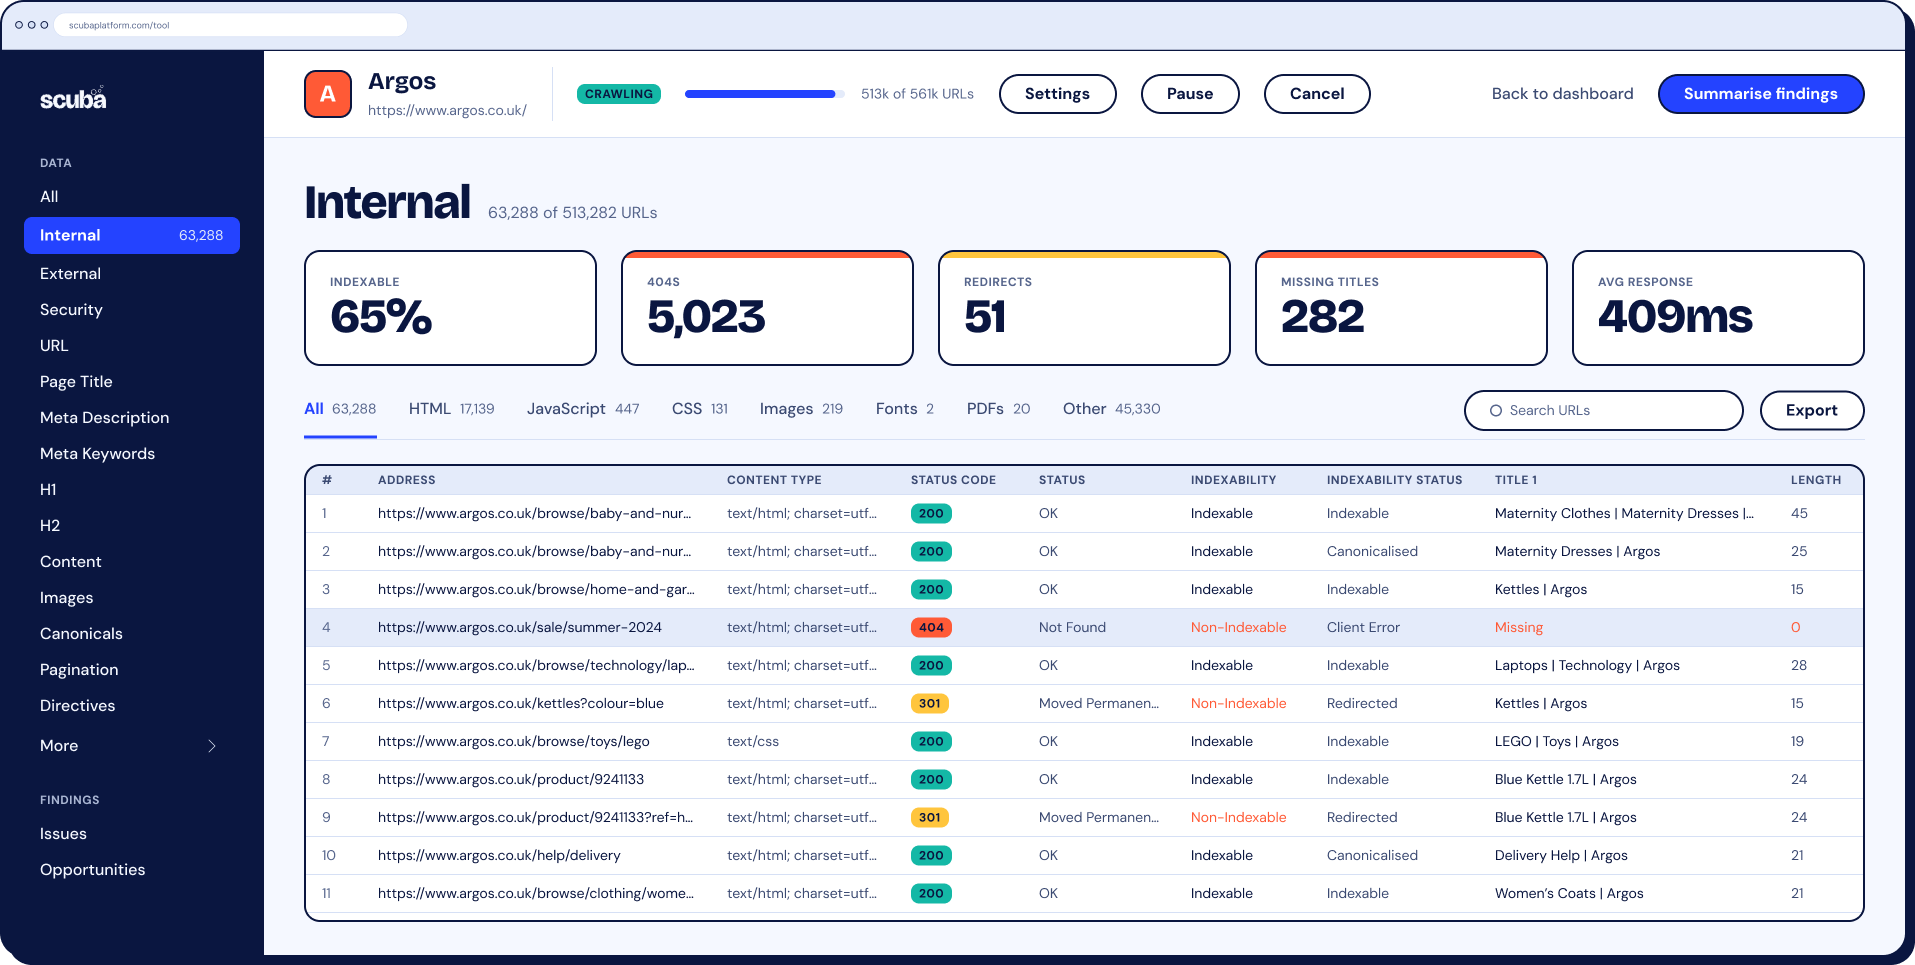
Find every URL
However your site is built, Scuba finds every page and every file. In the cloud, not on your laptop.
1,284,113
URLs crawled on one site. Laptop untouched.
Leaves no stone unturned
No matter the size of your website, Scuba finds every URL.
836
URLs found from the
homepage
Spider, list and compare
Crawl from the homepage, upload a list, or run 2 crawls side-by-side.
+38
links found after JS ran
JavaScript rendering
A real browser catches links that only appear after JS runs. Or crawl raw HTML.
Every resource logged
CSS, scripts, images, video, audio and documents, logged next to your pages.
User-agent: Googlebot
Speed: 5 URLs/sec
Limit: 1,500,000 URLs
Full crawl control
Set the user agent, headers, speed and limits.
Check every page
The same full audit on every plan. Your plan changes how much you crawl, never what gets checked.
Broken links and errors
404s, server errors and redirect chains, each with the pages linking to it.
Speed
PageSpeed Insights and Core Web Vitals for every page you crawl.
On-page basics
Every title, meta description and heading. Missing, duplicated, and length.
Indexing signals
Canonicals, hreflang, robots, and sitemaps are all checked.
Internal linking
Anchor text, crawl depth and orphan pages. See where link equity ends up.
Duplicate content
Exact and near-duplicates flagged before they split your rankings.
"@type": "Product",
"offers": { … }
✓ Valid
Structured data
Schema extracted and validated against what search engines expect.
Security
Security headers, mixed content and insecure forms, found and listed.
A sample of what gets checked. The full feature list is further down this page.
See the full listProve the fix landed
Compare runs, track changes and send the data wherever it needs to go.
1,204
issues last week
312
issues today
Crawl comparison
2 crawls side-by-side, with URL mapping so staging lines up with live.
Change tracking
What's new, fixed or broken since the last run.
836
rows sent to Sheets
Export anywhere
Download as CSV or send it straight into Google Sheets.
Scheduling and alerts
Run crawls daily, weekly or monthly and get pinged when they finish.
Bring the crew
Bigger plans add the bits that matter when more than one person is crawling.
MCP
Plug into your AI tools
Pipe crawl data into agents and assistants. Standard and Pro.
5
Crawls at once
2 on Standard, 5 on Pro. No queueing behind the big site.
∞
Seats for the team
10 users on Standard, unlimited on Pro.
12
Months of history
Keep a year of crawls, so you can prove what changed.
What you get in every plan
Your plan decides how much and what you can crawl, not what gets checked.
| Feature | Free | Lite | Standard | Pro | Enterprise |
|---|---|---|---|---|---|
| Crawl | |||||
| Spider, list and compare modes | |||||
| Custom search and extraction: CSS selectors, XPath and regex | – | ||||
| Render pages with JavaScript, or crawl the raw HTML | |||||
| Crawl and log CSS, scripts, imagery, video, audio and documents | |||||
| Crawl subdomains, not just the root domain | – | ||||
| Control the user agent, crawl speed, and device emulation type | |||||
| Override headers and limits | – | ||||
| Response times for every URL, grouped into bands | |||||
| Crawl sites in the cloud without straining your local hardware | |||||
| Integrations | |||||
| MCP access for AI assistants and agents | – | ||||
| Google Search Console: clicks, impressions, coverage, canonical conflicts and more | – | ||||
| Google Analytics: sessions, bounce rate, page value and more | – | ||||
| PageSpeed Insights: lab and field performance data for every URL | – | ||||
| Audit | |||||
| Page titles, meta descriptions and heading structure | |||||
| Canonicals, hreflang and robots directives | |||||
| XML sitemaps | – | ||||
| Orphan pages, compared against your sitemap | – | ||||
| Broken links, server errors and redirect chains | |||||
| Internal linking, anchor text and crawl depth | |||||
| Duplicate content, both exact and near-duplicate | |||||
| Semantic similarity and low-relevance content | |||||
| Structured data extraction and validation | – | ||||
| Core Web Vitals for every page, with the fixes Google suggests | – | ||||
| Mobile checks: viewport, tap targets and font size | – | ||||
| HTML validation on every page | |||||
| Security headers, mixed content and insecure forms | |||||
| Issues and findings grouped by priority | |||||
| Compare and report | |||||
| Compare two crawls side-by-side, with URL mapping for staging and more | – | ||||
| Track what changed since the last run | – | ||||
| Site tree with URL counts for every folder | |||||
| Export to CSV or directly into Google Sheets | |||||
| Schedule crawls and be alerted when they finish | – | ||||
| Annotate key fixes and tag team members | – | ||||
See what your
site is hiding
Cloud crawls on sites of any size, from your first 500 URLs to your millionth. Nothing to install, no fans screaming, no waiting around.
Launching 9 December 2026
Launching 9 December 2026